DevOps & Observability
Monitoring a Data Platform: What Should You Actually Measure?
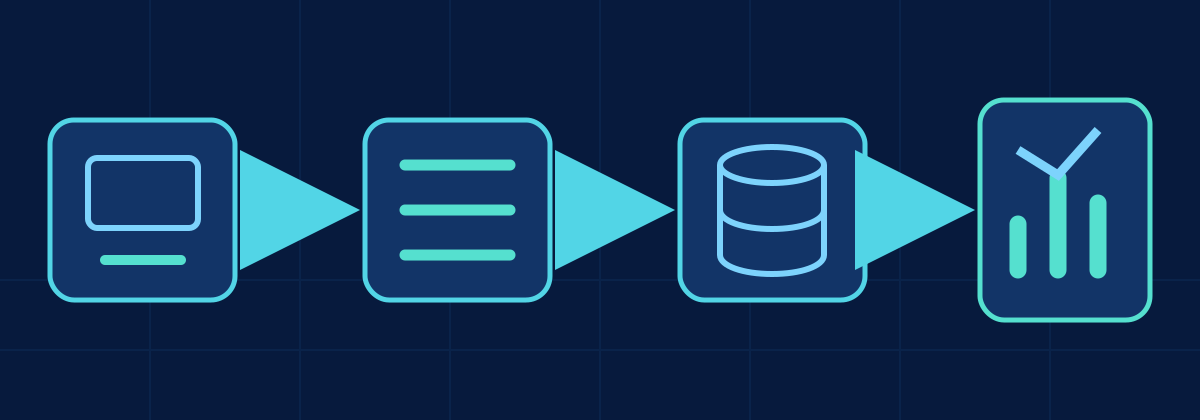
A practical monitoring model connecting clients, applications, APIs, report engines, data platforms, compute and storage.
On this page
Short answer: measure each layer a request crosses (client, application, API, report or query service, data platform, compute and storage) with the same four questions: how much work arrived, how much failed, how long it took at P50/P95/P99, and how close the layer is to saturation. Then add data freshness, which no infrastructure metric will tell you. Tie all of it together with one correlation ID so an incident can be followed across layers instead of guessed at.
Monitoring layers
Follow the request from User or Client to Application, API, Report Engine, Data Platform, and finally Compute and Storage. Keep one correlation identifier across those boundaries. The client view supplies perceived latency; the application supplies feature and error context; the API supplies rate and status; the report engine separates validation, cache, and query work; the platform exposes SQL, pipeline, and notebook execution; compute and storage expose saturation and I/O.
- ClientPerceived latency, errors the user saw
- ApplicationFeature, user action, exception context
- APIRequest rate, status codes, throttling
- Report or query serviceValidation, cache hit or miss, query time
- Data platformSQL requests, pipeline and notebook runs
- Compute and storageCPU, memory, capacity units, I/O
Evidence types
Metrics are numeric time series suited to aggregation and alerts. Logs describe individual occurrences. Events record meaningful changes such as deployments or retries. Traces connect timed spans across services. Audit data records who requested or changed what. They have different retention and access needs, but shared identifiers and UTC timestamps make them useful together.
What to measure
Measure request volume, error rate, P50, P95 and P99 latency, concurrent requests, queue depth, cache hit rate, CPU, memory, reads, writes, waits, query duration, pipeline duration, notebook duration, failures, retries, rows processed, and data freshness. Pair every rate with a denominator and every duration with workload size and class.
The first four are Google SRE’s “four golden signals” (latency, traffic, errors, saturation). Freshness is the one data platforms add: a pipeline that succeeds on time but loads yesterday’s file is healthy by every infrastructure metric and wrong for every user.
Why averages fail
If most requests finish in milliseconds while a few take tens of seconds, the average describes almost nobody. P50 shows typical behavior, P95 exposes the slow edge, and P99 reveals rarer tail behavior. Include sample count and segment by report type, cache outcome, tenant class, result size, and success state.
Where the signals live in a Microsoft data platform
You rarely need a new tool to start; most of these signals already exist. The work is deciding which ones you keep, for how long, and how they join.
| Layer | Signals worth keeping | Where they come from |
|---|---|---|
| Client and application | Page or action latency, failed requests, exceptions, dependency calls | Application Insights (Azure Monitor) |
| API | Requests per consumer, 4xx/5xx and 429 rates, backend latency | Azure API Management analytics and diagnostic logs |
| Report or query service | Cache hit rate, validation rejections, queue time vs query time | Your own structured log, one row per request |
| SQL Server | Waits, blocking, CPU, reads, plan regressions | DMVs (sys.dm_exec_requests), Query Store, Extended Events |
| Fabric Warehouse / SQL endpoint | Query duration, frequent and long-running queries | queryinsights.exec_requests_history, queryinsights.long_running_queries |
| Fabric pipelines and notebooks | Run status, duration, failures, retries | Monitoring hub, Spark monitoring, your execution log |
| Fabric capacity | CU usage, smoothing, throttling and rejection | Microsoft Fabric Capacity Metrics app |
Two of these deserve a deliberate design rather than defaults: the request log of your own service and the execution log of your pipelines. Platform tools show what ran; only your logs show which client, tenant, report or business load it ran for. Designing execution logs for data pipelines covers the pipeline side.
Alerts versus dashboards
A dashboard is for looking around; an alert is a request for someone to act. Alert only when the receiver has a documented response, and write the response before the rule.
| Alert condition | Why it matters | First response |
|---|---|---|
| API P95 latency above objective for 10 minutes, with traffic normal | Users are waiting and it is not just load | Split by cache outcome and dependency; follow the slowest correlation IDs |
| 429 or 5xx rate above baseline for one consumer | A client is throttled or a backend is failing | Check that consumer’s volume against its quota; see measuring API and report request volume |
| Blocking chain older than a few minutes on SQL Server | Work is queued behind one session | SQL Server blocking runbook |
| Fabric capacity in interactive delay or rejection | Every workload on the capacity is affected | Fabric capacity saturation runbook |
| Freshness: latest successful load older than its schedule plus tolerance | Reports show stale data while every job looks green | Check the execution log for the last successful batch and its source watermark |
| Pipeline failed after retries exhausted | The retry budget did not absorb a transient fault | Read the first error, not the last; confirm whether partial data was written |
Everything else (CPU, memory, cache hit rate, queue depth, row counts) belongs on a dashboard first. Promote a signal to an alert only after you have seen it predict a user-visible problem.
A minimum set for the first workload
Pick one workload that matters and get these working end to end before adding more:
- One correlation ID created at the edge and carried into every log line, query label and pipeline parameter.
- A structured request or execution log with UTC start and end, status, duration, rows or bytes, and error code.
- P50/P95/P99 latency and error rate for that workload, segmented by its main class (report type, pipeline, tenant tier).
- A freshness check per published dataset: when was it last loaded successfully, and from which source batch.
- Saturation for the compute it runs on: SQL Server waits and CPU, or Fabric capacity utilization.
- Two or three alerts from the table above, each with an owner and a written first response.
Expand to the next workload only when an on-call engineer who did not build the first one can go from “the report is slow” to a specific request, query or notebook run using these signals alone.
Where to go next
- Monitoring Microsoft Fabric pipelines and notebooks in production
- Monitoring SQL Server workloads in real time
- Fabric capacity and compute usage, and the Fabric Capacity Planner for sizing from utilization you already have
- Query Store and performance regressions
Sources
- Google SRE book: Monitoring distributed systems (the four golden signals)
- W3C: Trace Context (propagating one trace ID across services); OpenTelemetry: Signals
- Microsoft Learn: Application Insights overview, Query Store, Extended Events
- Microsoft Learn (Fabric): Query insights, Monitoring hub, Spark monitoring, Capacity Metrics app
Product sources checked November 2026. Fabric monitoring surfaces change often; confirm feature names against the linked pages.
Was this helpful?
What could be better?
Thanks — that helps me improve Javi Builds.
Continue learning
- Cheat sheetChoosing the Right AI ModelA practical framework for choosing an AI model for data applications: when not to use an LLM, which dimensions matter, a decision tree, and how to evaluate candidates on quality, latency and cost per successful task.Open cheat sheet
- ArticleMonitoring Microsoft Fabric Pipelines and Notebooks in ProductionHow to monitor Fabric pipelines and notebooks well enough to catch failures, slowdowns, retries, capacity pressure and bad data before users do, with run correlation, execution logs, baselines and alerts.Read article
What should I build next?
I'm building Javi Builds around practical problems data engineers actually face. Tell me what you'd like to see next.
Stay in the loop
Get the Javi Builds updates you actually care about.
Check your inbox
I sent you a confirmation link. Your subscription will be active after you confirm it.