Microsoft Fabric
Using Session Tags in Fabric Pipelines
Use Microsoft Fabric pipeline session tags to group compatible notebook activities for Spark session reuse while preserving workload boundaries.
On this page
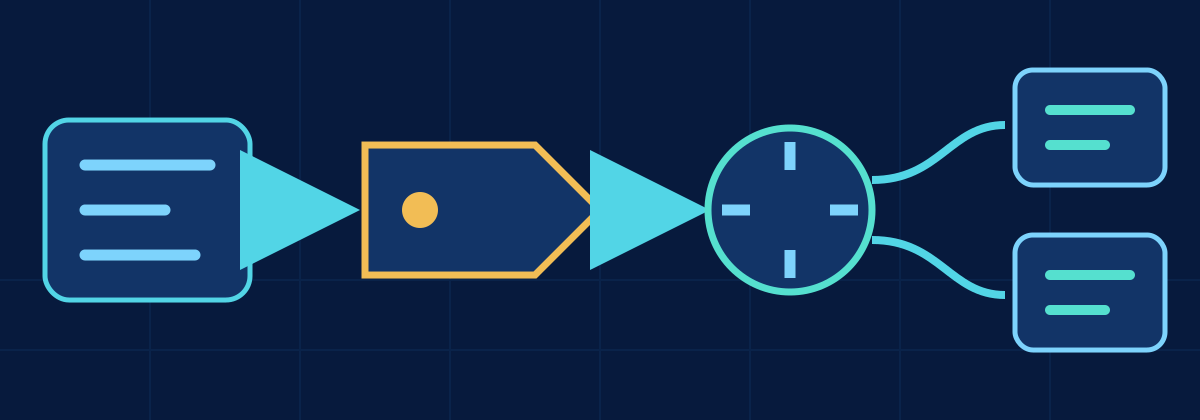
Short answer: a session tag tells a Fabric pipeline which notebook activities may share one high-concurrency Spark session. Activities with the same tag, run by the same user with the same workspace, default Lakehouse, compute configuration and libraries, can join a session that is already running instead of each starting their own. That removes repeated session startup and, because only the activity that started the shared session is billed, can reduce cost. Use one tag for short, related, compatible notebooks; give memory-heavy or isolation-sensitive work its own tag.
- Notebook activityOne of several notebooks in a pipeline
- compatibleShared tagSame user, Lakehouse, compute and libraries; short steps
- heavyOwn tagLarge shuffles or caches, strict isolation needs
- incompatibleNo sharing possibleDifferent environment, Lakehouse or identity
Problem
A pipeline runs several notebooks under the same operational workflow. Each notebook is correct on its own, but repeated startup makes the end-to-end duration noisy. You want reuse without mixing unrelated workloads or assuming that a matching string overrides compatibility and isolation rules.
What a session tag does, and what it does not
In high-concurrency mode, one Spark application hosts several notebooks, each in its own REPL core, so local variables in one notebook do not overwrite another’s. Executors are shared and allocated across those REPL cores with FAIR scheduling.
A session tag:
- groups notebook activities in a pipeline as candidates for the same shared session;
- removes repeated startup for every activity that joins a session already running;
- changes billing: only the activity that starts the shared session is billed.
A session tag does not:
- override compatibility. Sharing requires the same user, workspace, default Lakehouse, Spark compute configuration and library packages. Otherwise Fabric starts another session.
- work by itself. A workspace admin must enable For pipeline running multiple notebooks in the workspace’s high-concurrency settings.
- guarantee one session. By default up to five notebooks share a session; the limit is configurable up to 50. Capacity and packing rules can create additional sessions.
- share state. Variables are isolated per notebook; data must move through tables, files or parameters.
Practical recommendations
Choose a tag that represents an execution compatibility group, not merely a business label. Notebooks in one daily sales pipeline may belong together if they use the same Lakehouse, environment, Spark settings, identity boundary, and overlapping schedule. A finance transformation and an experimental machine-learning notebook should not share a tag only because both run in the same workspace.
Keep tag construction deterministic. A stable value such as sales-daily-standard makes related activities candidates for reuse across the intended window. Adding a unique run identifier to every tag prevents cross-activity reuse because every activity presents a different value. Conversely, using one global tag for every pipeline creates an overly broad group and makes behavior harder to reason about.
Separate incompatible workloads deliberately. A notebook with different compute requirements, libraries, or default Lakehouse should use a different group even when it is part of the same business process. Isolation may also be more important than startup for memory-heavy or latency-critical jobs.
Measure at both levels. Record pipeline activity duration and notebook-stage duration. In high concurrency, monitoring provides notebook-related views and separated logs, which are essential when several notebooks share the underlying application. A shared session can improve acquisition while Spark work inside it remains slow or contended.
Example: Validate → Transform → Merge → Summarize
A daily sales pipeline runs four notebooks in sequence. Validate checks file arrival and schema; Transform cleans and conforms Silver data; Merge upserts into a large Gold Delta table; Summarize builds small aggregates for reporting. All four use the same Lakehouse and environment.
| Scenario | Reuse session? | Why |
|---|---|---|
| Validate, Transform and Summarize: short, sequential, same settings | Yes, one tag such as sales-daily-standard |
Each would otherwise pay session startup; they use little memory |
| Merge rewrites a large target with a heavy shuffle | Usually a separate tag | It shares executors with every notebook in the session; spill or contention slows them all |
| One step needs extra libraries in a different environment | No, different tag | Different libraries prevent sharing anyway; a shared tag only misleads |
| Steps run in parallel and cache large DataFrames | Test before sharing | Memory and executors are shared even though variables are not |
| A step must run under another identity or default Lakehouse | No | Sharing requires the same user and default Lakehouse |
| Steps need to exchange data | Not a tag decision | Pass data through tables or parameters, never through session memory |
Pass a pipeline correlation identifier as a notebook parameter rather than encoding it into the session tag. That preserves a stable reuse group while keeping logs traceable.
# Parameter cell values supplied by the pipeline
pipeline_run_id = ""
processing_date = ""

print({
    "pipeline_run_id": pipeline_run_id,
    "processing_date": processing_date,
    "stage": "build_silver_orders",
})Operational cautions
- Incompatible environments. Two notebooks with the same tag but different environments or default Lakehouses will not share; the tag then hides the real grouping. Keep one tag per environment and Lakehouse combination.
- Memory pressure. A session’s executors serve every notebook in it. One large merge, wide join or cache can push the others into spill. Measure stage times and spill per notebook before and after grouping.
- State-leakage assumptions. Two opposite mistakes: relying on another notebook’s variables (they are isolated), and assuming nothing is shared (compute, memory and disk are).
- Long-lived sessions. A shared session stays up while activities keep joining, and a long notebook holds it for everyone. Check the session limit when many activities run at once, and expect a new session (and its startup) after the session ends.
- Debugging. Monitoring shows the shared Spark application and per-notebook views; confirm which activities actually joined before attributing a speed-up to the tag. A naming convention such as
<domain>-<cadence>-<profile>(sales-daily-standard,sales-daily-heavy) makes the grouping readable in run history.
Common mistakes
- Setting a tag without enabling the workspace’s pipeline high-concurrency option.
- Assuming identical tags can override different Lakehouses, compute settings, libraries, or user boundaries.
- Putting a unique run ID in each activity’s tag and accidentally disabling reuse.
- Giving every notebook in the workspace one tag.
- Depending on another notebook’s in-memory variables or cache as a pipeline interface.
- Combining resource-heavy concurrent activities without measuring contention.
- Looking only at end-to-end duration and not separating session acquisition from Spark work.
- Assuming one tag always maps to one physical session; capacity and platform packing rules can create additional sessions.
What to check next
Confirm the high-concurrency workspace setting, then inspect each activity’s default Lakehouse, environment, compute settings, libraries, identity, and tag. In monitoring, verify which sessions and notebook jobs were created and whether the expected activities were associated with the shared run.
If reuse does not occur, treat compatibility as the first hypothesis. If reuse occurs but the pipeline remains slow, examine concurrency, Spark stages, shuffle, I/O, and writes. If reliability declines under shared execution, reduce the group or isolate the conflicting workload. The correct session strategy depends on workload compatibility, resource behavior, and operational clarity—not on maximizing reuse at all costs.
Related
- Increase the high-concurrency notebook session limit
- How to reduce Fabric notebook startup time
- How to make Microsoft Fabric notebooks faster
Sources
- Microsoft Learn: High concurrency mode in Apache Spark for Fabric (REPL isolation, scheduling, billing, session limit), Configure high concurrency mode for notebooks in pipelines (sharing conditions, workspace setting, session tags)
Checked against Microsoft Learn in November 2026. The pipeline page still describes a five-notebook maximum; the overview documents the configurable limit.
Was this helpful?
What could be better?
Thanks — that helps me improve Javi Builds.
Continue learning
- Cheat sheetFabric Session TagsUse Microsoft Fabric session tags to reuse compatible Spark sessions across notebook activities, reduce startup overhead, and avoid unnecessary session fragmentation.Open cheat sheet
- RoadmapMicrosoft Fabric Notebook PerformanceUse Microsoft Fabric pipeline session tags to group compatible notebook activities for Spark session reuse while preserving workload boundaries.View roadmap
What should I build next?
I'm building Javi Builds around practical problems data engineers actually face. Tell me what you'd like to see next.